CALIBURN: Self-Calibrated LLM Unlearning Alignment
Reformulates LLM unlearning as policy-level preference optimization with a self-calibrated margin derived from the model's own confidence — eliminating the need for a static reference model or retention data, and reaching state-of-the-art forget–retain trade-offs on WMDP and MUSE under scarce and heterogeneous unlearning data.
Aug 2026
CALIBURN Accepted to EMNLP 2026 Main Conference
Our paper "CALIBURN: Self-Calibrated LLM Unlearning Alignment" has been accepted to the EMNLP 2026 Main Conference.
Aug 2026
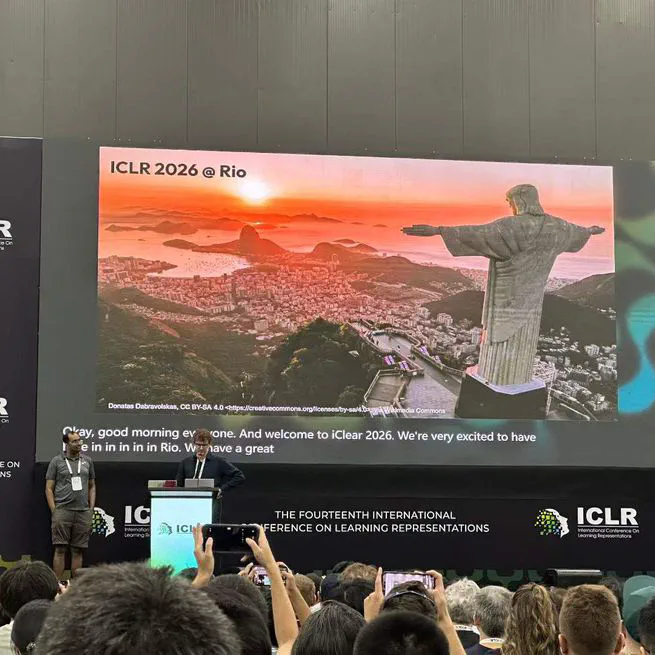
Presented DUET at ICLR 2026 in Rio de Janeiro
I travelled to Rio de Janeiro, Brazil to present our ICLR 2026 paper DUET, and came back with a notebook full of ideas.
Apr 2026

DUET: Distilled LLM Unlearning from an Efficiently Contextualized Teacher
The first work to introduce on-policy distillation for LLM unlearning — a prompt-conditioned teacher dynamically elicits the desired forgetting behavior and distills it into the student via Top-K logit alignment, giving strong forget–retain trade-offs and robustness to reverse prompts and task-format shifts.
Apr 2026